AlphaProtein Novo: an inspectable enzyme-design pipeline
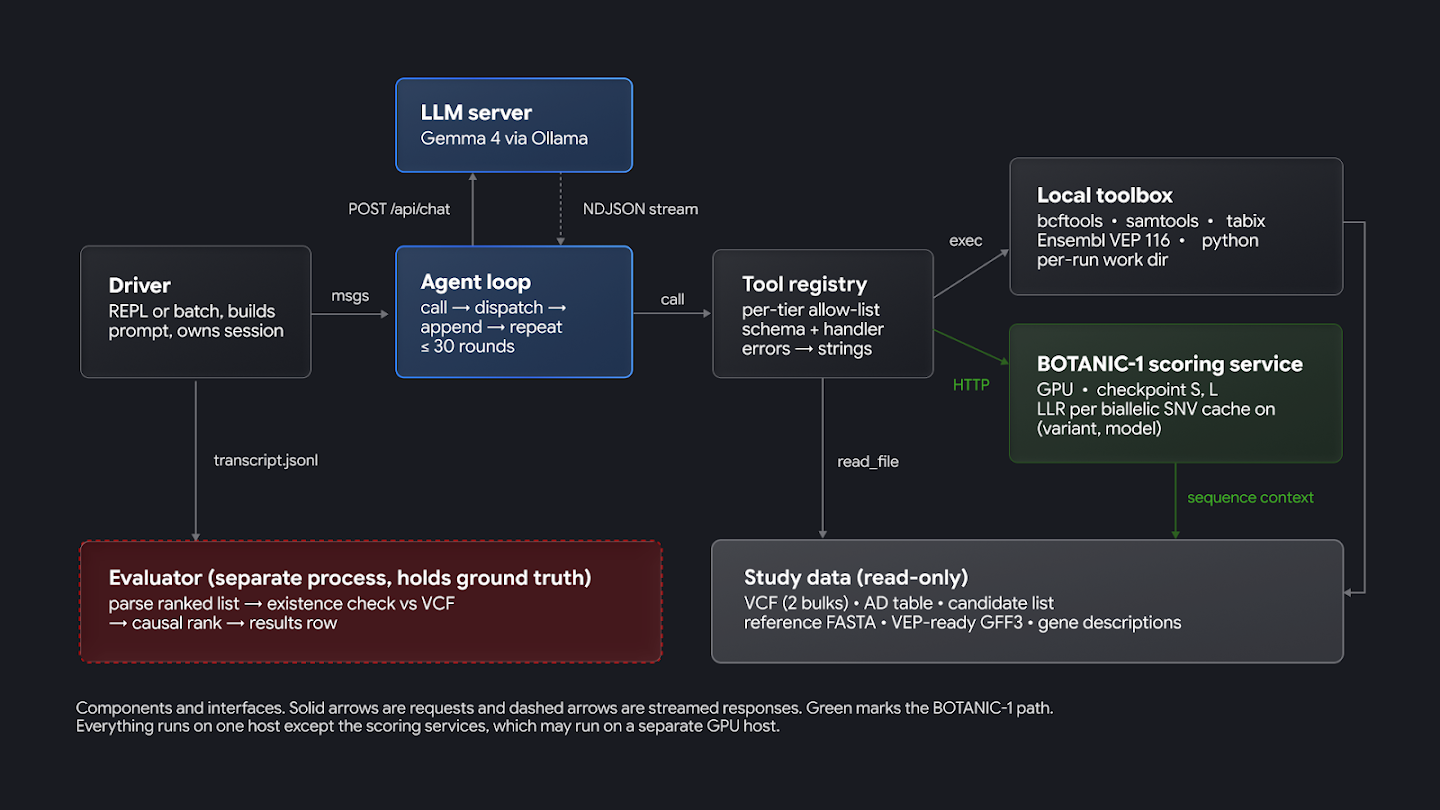
The repository separates generation, sequence redesign, structure prediction, and evaluation.
AlphaProtein Novo source repository card. Credit: Google DeepMind · GitHub repository card. Original image ↗
AlphaProtein Novo is a diffusion-based pipeline for de novo enzyme design. Its official repository describes a generator conditioned on catalytic motifs and ligand context, producing protein structures and sequences.
Think in terms of a pipeline and an experiment
Protein design involves more than producing a sequence that looks plausible. A candidate has to satisfy the structural and chemical constraints of the intended task, and computational screening must be followed by the appropriate experimental work.
AlphaProtein Novo organizes generation and evaluation as connected stages. That organization matters for reproducibility: a result should remain traceable to its input specification, selected model parameters, generated candidate, and evaluation settings. A favorable predicted structure is evidence from a model, not a laboratory observation.
Follow the stages
| Stage | Role |
|---|---|
| Generation | Produce candidate structures and sequences |
| Optional sequence redesign | Refine sequences with LigandMPNN |
| Structure prediction | Evaluate predicted structures with AlphaFold 3 |
| Evaluation | Calculate the campaign’s configured metrics |
A manifest defines the design campaign. The pipeline writes outputs into stage-specific directories and records metadata for the generated designs.
Work through a screening funnel
A design campaign produces candidates that pass through several tests. To understand the accounting, imagine generating 1,000 candidates, retaining 200 after a structural screen, then selecting 40 after another criterion. These counts are an illustrative campaign, not AlphaProtein Novo's reported experimental yield.
Twenty percent survives each of the two successive screens in this example, and four percent of the original set remains. The denominators matter. Describing the last stage as “20% retained” without naming its input would hide that 96% of the original candidates have already been removed. The chart keeps the stages and counts visible, so the reader can trace which population a proportion describes.
The retained count is not an activity measurement. A candidate might satisfy a predicted shape criterion and still be difficult to express, unstable under the intended conditions, or inactive in an assay. Similarly, selecting a smaller set does not show that the screen enriched for useful enzymes unless the relevant experimental outcomes support that conclusion. Keep screening metrics, selection decisions, and measured properties in separate columns of the campaign record.
Preserve the link from candidate to assay
A useful record includes a stable candidate identifier, generation configuration, any redesigned sequence, predicted structure, screening values, and the reason it was selected. If experimental data later arrives, it should be attached to the correct sequence rather than to a similarly named file. A sequence redesign creates a new artifact whose relationship to the original must remain explicit.
The catalytic motif and ligand context define important constraints on the design. A plausible overall fold does not establish that the relevant local geometry and chemistry support the requested reaction. Read the campaign specification alongside the evaluation settings. When comparing two campaigns, retain the same assay and selection criteria or identify the difference directly. These practices let a reader distinguish a proposal, a computational prediction, and an experimentally supported result. The pipeline diagram and arithmetic are reading aids for this chain of evidence, not a claim that Qentrah generated or experimentally tested proteins.
Screening counts need stage-specific denominators
- Design specification
- Generated candidates
- Computational screening
- Selected candidates
- Experimental assay
Focus the graph and use arrow keys, or tap a point, to inspect values. The complete data table is available below.
View data table
| Category | Candidates |
|---|---|
| Generated | 1000 |
| Screen 1 | 200 |
| Screen 2 | 40 |
Code and weights are separate
The source repository does not include pretrained weights. The README documents downloads and distinguishes the terms governing code, model parameters, and generated outputs. Read those documents before using or distributing the corresponding artifacts.
The examples use different environments for the primary pipeline and optional LigandMPNN stage. Follow the environment instructions rather than assuming every dependency belongs in one installation.
Prepare dependencies as separate requirements
The repository’s setup guide distinguishes a main JAX environment from an optional LigandMPNN environment. It also documents model parameter locations and preparation of the chemical component data used by AlphaFold 3.
Before running the documented example, list the stages you actually need. Confirm their Python and accelerator requirements, parameter files, and any optional sequence-redesign dependencies. Use the repository’s current instructions rather than mixing commands from several unrelated tutorials.
Keep the generator and structure-prediction parameter terms with the corresponding downloads. The source code and the model parameters have separate terms, so the repository’s visibility cannot answer every licensing question.
Make the first result auditable
Start from the supplied example or input manifest. Preserve it unchanged for the first run, and save the configuration and evaluation outputs with the candidates. Then alter one design requirement and compare the effect. If a stage fails, report which stage and input failed instead of describing the whole pipeline as working.
For a scientific claim, state whether the evidence comes from generated structures, predicted metrics, or physical measurements. This article is a guide to reading and preparing the published workflow; we have not run a protein-design campaign or performed experimental validation.